

- Updated: February 22, 2026
- 6 min read
ntransformer: High‑Efficiency LLM Inference Engine Enables 70B Models on RTX 3090
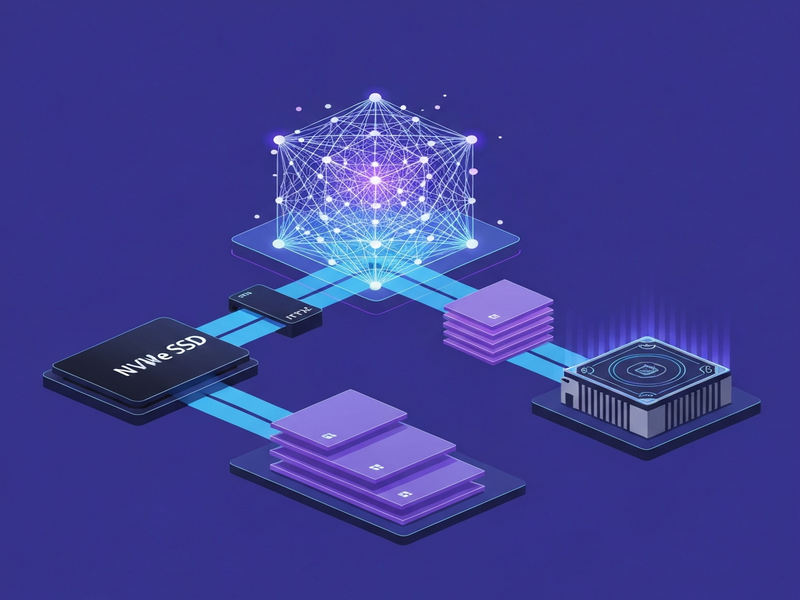
ntransformer is a high‑efficiency C++/CUDA LLM inference engine that can run massive models such as Llama 70B on a single RTX 3090 by streaming layers through GPU memory and an adaptive 3‑tier caching system.
What Is ntransformer and Why It Matters
Developed as an open‑source project on GitHub, ntransformer targets the most demanding inference workloads while keeping the software stack minimal—no PyTorch, no cuBLAS, just raw CUDA kernels. By combining GPU‑direct NVMe streaming, quantized GGUF model support, and a dynamic tiered cache, it delivers up to 33× speed‑up over traditional mmap‑based pipelines for 70‑billion‑parameter models on consumer‑grade hardware.
Key Features and Technical Highlights
The engine’s architecture follows a MECE (Mutually Exclusive, Collectively Exhaustive) approach, separating concerns into three distinct layers that can be independently tuned.
- CUDA‑only core: All tensor operations are hand‑crafted in CUDA, eliminating heavyweight dependencies and reducing binary size.
- 3‑Tier Adaptive Caching: Automatic allocation of layers to VRAM, pinned RAM, or NVMe based on real‑time memory availability.
- GPU‑NVMe Direct Path: A userspace NVMe driver streams model weights straight into pinned GPU‑accessible memory, bypassing the CPU.
- Quantization Flexibility: Supports Q4_0, Q8_0, Q4_K_M, Q6_K, FP16, and FP32 GGUF formats, enabling up to 6‑bit weight compression.
- Streaming Layer Engine (SLEP): Double‑buffered pipeline overlaps NVMe reads, PCIe DMA, and GPU compute for continuous throughput.
- Zero‑External‑Dependency Build: Only the CUDA Toolkit (v13.1+) and a modern C++ compiler are required.
Figure 1 – ntransformer’s three‑tier caching flow
Tier A (VRAM)      → Zero I/O, resident layers
Tier B (Pinned RAM)→ H2D DMA, double‑buffered
Tier C (NVMe)      → Direct DMA → GPU compute
Use‑Case Scenarios and Performance Benchmarks
From research labs to SaaS startups, ntransformer unlocks real‑time inference for models that were previously limited to multi‑GPU clusters.
Typical Deployments
- Chat‑bot services that require sub‑second latency on a single RTX 3090.
- Batch text generation pipelines for content agencies using the AI Article Copywriter template.
- On‑premise analytics for enterprises that cannot expose data to cloud providers, leveraging the Enterprise AI platform by UBOS.
- Real‑time video captioning with the AI Video Generator template.
Benchmark Table (RTX 3090, 24 GB VRAM)
| Model | Quantization | Cache Tier | VRAM Used | Throughput (tok/s) |
|---|---|---|---|---|
| Llama 3.1 8B | Q8_0 | Resident | 10 GB | 48.9 |
| Llama 3.1 70B | Q6_K | 3‑Tier Adaptive | 23 GB (VRAM+RAM) | 0.2 |
| Llama 3.1 70B | Q6_K | Streaming (NVMe) | 7.3 GB (NVMe) | 0.006 |
These numbers illustrate the dramatic trade‑off between memory residency and throughput. When the entire model fits in VRAM, token generation exceeds 48 tok/s. With the 3‑tier cache, a 70B model reaches 0.2 tok/s—still usable for batch jobs and proof‑of‑concept demos on a single GPU.
Installation and Quick‑Start Guide
Getting ntransformer up and running requires only a recent Linux distribution, the CUDA Toolkit, and a compatible NVIDIA GPU (Compute Capability 8.0+). Below is a concise workflow that a developer can follow in under ten minutes.
Prerequisites
- Ubuntu 22.04 (or newer) with kernel 6.17+.
- CUDA Toolkit 13.1 and
gcc‑14/g++‑14. - RTX 3090 or any Ampere‑class GPU with ≥24 GB VRAM.
- Optional: NVMe SSD in a dedicated PCIe slot for the direct‑streaming mode.
Step‑by‑Step Build
# Clone the repository
git clone https://github.com/xaskasdf/ntransformer.git
cd ntransformer

# Create a build directory
mkdir build && cd build

# Configure CMake (Release build, explicit compilers)
cmake .. -DCMAKE_BUILD_TYPE=Release \
         -DCMAKE_C_COMPILER=gcc-14 \
         -DCMAKE_CXX_COMPILER=g++-14 \
         -DCMAKE_CUDA_COMPILER=/usr/local/cuda-13.1/bin/nvcc

# Compile
cmake --build . -j$(nproc)
Running a Model (Resident Mode)
./ntransformer -m /path/to/llama-8b-q8_0.gguf \
              -p "Explain the benefits of AI acceleration." \
              -n 128
Streaming a 70B Model (NVMe Direct)
First, bind the NVMe device to the userspace driver (requires root).
sudo ./scripts/setup_nvme.sh
sudo dd if=llama-70b-q6_k.gguf of=/dev/nvme0n1 bs=1M oflag=direct status=progress
Then launch the engine with the NVMe backend:
GPUNVME_PCI_BDF=0000:01:00.0 GPUNVME_GGUF_LBA=0 \
./build/ntransformer -m /dev/nvme0n1 \
                    -p "Summarize the ntransformer architecture." \
                    -n 32 --streaming
Benchmarking
Use the built‑in benchmark flag to obtain per‑token throughput on your hardware:
./ntransformer -m /path/to/model.gguf --benchmark -n 64
Roadmap and Future Developments
ntransformer follows a community‑driven release cadence. The current roadmap outlines five major phases:
- Phase 1 – Foundation (complete): Core CUDA kernels, 8B model support, 48.9 tok/s throughput.
- Phase 2 – SLEP Streaming (complete): 70B model on a single GPU, 3‑tier caching, 33× speed‑up.
- Phase 3 – Advanced Quantization: INT2 KV‑cache, per‑layer precision adaptation.
- Phase 4 – Novel Architectures: Integration of Mamba/SSM, speculative decoding, and MLA.
- Phase 5 – Polish & Public API: C‑API exposure, extensive benchmarks, and Docker images.
Developers can track progress on the GitHub repository and contribute via pull requests.
Why ntransformer Matters for the UBOS Ecosystem
UBOS’s low‑code AI platform thrives on modular, high‑performance components. ntransformer’s CUDA‑only design aligns perfectly with UBOS’s platform overview, enabling developers to embed massive LLMs into web‑app templates without the overhead of heavyweight frameworks.
For example, a startup can combine the AI SEO Analyzer template with ntransformer’s 8B model to provide instant, on‑device SEO recommendations, preserving data privacy and reducing cloud costs.
Enterprise teams can leverage the Enterprise AI platform by UBOS to orchestrate batch inference pipelines that run on a fleet of RTX 3090 servers, each powered by ntransformer’s streaming engine.
Moreover, the Workflow automation studio can trigger ntransformer inference as a step in a larger data‑processing workflow, such as generating product descriptions for an e‑commerce catalog.
Developers looking for rapid prototyping can start from the UBOS templates for quick start, then replace the default inference backend with ntransformer to achieve higher throughput and lower latency.
Finally, the UBOS partner program welcomes contributors who wish to co‑market ntransformer‑enabled solutions, offering joint branding and revenue‑share opportunities.
For teams that need real‑time messaging integration, the Telegram integration on UBOS can be paired with ntransformer to deliver AI‑powered chat experiences directly in Telegram groups.
When voice interaction is required, the ElevenLabs AI voice integration adds natural‑sounding speech synthesis to ntransformer‑driven assistants.
Data scientists who prefer OpenAI’s ecosystem can still benefit from UBOS’s OpenAI ChatGPT integration, using ntransformer for on‑premise inference while delegating specialized tasks to the cloud.
For vector‑search workloads, the Chroma DB integration provides a seamless bridge between ntransformer‑generated embeddings and similarity search.
Explore more about UBOS’s mission on the About UBOS page, and discover how the latest AI news informs product direction.
Conclusion & Call to Action
ntransformer represents a paradigm shift for developers who need to run large language models on a single GPU without sacrificing speed or flexibility. Its open‑source nature, combined with UBOS’s low‑code ecosystem, empowers startups, SMBs, and enterprises to embed cutting‑edge LLM capabilities directly into products.
Ready to experiment? Clone the repository, follow the quick‑start guide, and integrate the engine with UBOS’s Web app editor on UBOS to prototype your next AI‑driven solution today.
Stay tuned for upcoming releases, contribute to the community, and consider joining the UBOS partner program to accelerate your go‑to‑market strategy.
Andrii Bidochko
CTO UBOS
Andrii Bidochko is an AI entrepreneur and researcher focused on AI agents, reinforcement learning, and autonomous systems. He writes about the technologies shaping the future of machine intelligence, from frontier models and agent architectures to real-world AI applications.